Technique 1 (the easy way) - Getting Lemonade-AI to run on Proxmox 9
Note: This pre-suppose that you are running proxmox 9.x (i.e. based on Debian Trixie) and you left some extra room on /dev/mapper/pve-root to fit a few GGUFs.
Hey kids, looks like you inherited a bunch of t740s (basically e-waste adjacent at this point), and you would like to put those useless Ryzen Vega iGPUs to work on Proxmox 9. It can't be offloaded (SR-IOV) cleanly, and blacklisting the device for docker just felt...odd.
How about tossing lemonade.ai onto it so you too can add a low parameter inferencing capability to the box?
Oh, you can't because of dependencies?
Here's how to fix it.
a) Add the missing repos
b) Add the dependency packages
c) Grab the debian packages for lemonade-ai server, autoresolve the issues and enable the lemonade server
d) Download and download amdgpu_top
e) Setup Lemonade to allow connections from outside localhost, and restart lemond
Now connect to it using lemonade-server and download/run some tests.
The HP t740 thin client
Is it useful in the context of a t740 (features a Ryzen embedded V1756B, which is the same as a Ryzen 5 2600H)?
Eeeeeh, marginally.
For example, if we download a small model (gemma-4-E2B-it) on a t740 (running proxmox 9.2) and run it with a context window of 32k, and by using the lemonade benchmark over 5 runs using this syntax:
We have:
TTFT = Time to FIrst Token (in milliseconds, lower number is better)
TPS = Tokens per second (higher number is better)
16 is slower than realtime (usually 25) but it's somewhat tolerable.
Does context window size matter on this machine? Kinda. Here's lowering the ctx to 8k to compensate for less compute firepower...very slight improvement in TTFT time and slightly higher tokenization rate.
Are we sure it's working off the Radeon Vega 8 Embedded iGPU?
Yeah it is. What about a more frontier model like Qwen 3.8 with 4 billion parameters, q=8?
Eeeeeh, it's working but 7 tokens/sec isn't my idea of functional.
The HP t755 Elite thin client
What about the t755 (its successor), which has a Ryzen embedded V2546 (same as a Ryzen 5 4600H)? Can anything fun be done with it when it goes onto the secondary market one day?
Okay, well, it just so happens that I have a t755 as my production hypervisor, so I can do some quick testing.
Note that if you compare the numbers it's about 20% faster (from 16 to 20 tps) despite the fact that the Radeon Graphics 384SP iGPU on the t755 is roughly the same in terms of texture/FP performance as the Vega 8 Embedded iGPU on the t740 (the pixel rate is higher on the 384SP but not by much, roughly 15-20% higher)
So, eh, how do we know it's working?
What about the same trick with lowering ctx? Slight improvement but not by much.
What about Qwen 3.8? TTFT is significantly better but token-walking still suck.
20tps on Gemma-4 is almost about useful. Although I would be extremely cautious/skeptical about its factuality.
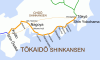
(at least 4 of those stations exist on another route coming out northwest of Tokyo, the train route is generally a south/southwest route, Kobe is west of Osaka on a completely different line, and both Atami and Odawara (major beachside resorts in the Kanto region) are both misreported as not being stops on the Tokaido Shinkansen. Hoooh boy...)
OFF-TOPIC
Comparison / e-Peen measurement with the Minisforum N5 Air, with or without AMD Radeon Pro V620 acceleration
In contrast, here's the Minisforum N5 Air (Ryzen 7 255H, same as a Ryzen 8845HS but with its useless XDNA NPU disabled) using its Radeon 780M iGPU on Debian 14 (should work on Debian 13). ROCm support for the 780M was added in Lemonade 11.6.
Note the much lower TTFT numbers due to the 780M having stronger compute overall (RDNA3.5 instead of Vega 2 GPU architecture).
If you have a strix Halo, the 780M is about 1/2 to 1/3 the computing firepower of your Radeon 8060S and with double 1/2 the RAM bandwidth, and based on benchmarks from Strix halo machines versus the 780M the numbers do jive with that difference.
Here's Gemma-4 E2B on the 780M, with Vulkan and ROCm respectivelyy...
And here's Qwen 3.8 with 4 billion parameters, condensed on quantization level 8, Vulkan and ROCm.
And here with its Radeon Pro V620 off an Oculink eGPU dock on Vulkan mode.
Gemma-4-E2B...Vulkan and ROCm
Qwen 3.8, Vulkan and ROCm

Yeah, TTFT is faster here but token walking is slower on ROCm.
Note that TTFT isn't much lower overall on the V620 versus the 780M, but the token walk rate is much better.
That hints to the RDNA3.5 compute units on the 780M being faster on a per-CU basis (but with less CUs than the V620 so it loses overall), but the higher token walk rate on the V620 is a direct correlation of its higher in-device memory bandwidth.
So, what does the V620 look like with its VRAM (32GB) maxed out and spilling over?
Here's Vulkan and ROCm on an 80B parameter, A3B model, which uses up ~30GB of VRAM out of the 48 needed (the rest will go to GTT/DDR5 system RAM).
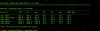
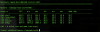
And what about inferencing off the 780M using DDR5 system memory? Is the numbers that much worse?
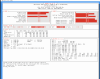
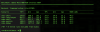
Eh, I would say that paradoxically for certain tasks the 780M is not that far off from the V620...maybe about 1/3 slower...and for the code explain/debug tasks the 780M is actually almost-as-fast as the V620 and on Vulkan, even slightly faster on first token/prompt processing rate.
We'll need to see if the benchmark numbers jive with actual experiences.
Note: This pre-suppose that you are running proxmox 9.x (i.e. based on Debian Trixie) and you left some extra room on /dev/mapper/pve-root to fit a few GGUFs.
Hey kids, looks like you inherited a bunch of t740s (basically e-waste adjacent at this point), and you would like to put those useless Ryzen Vega iGPUs to work on Proxmox 9. It can't be offloaded (SR-IOV) cleanly, and blacklisting the device for docker just felt...odd.
How about tossing lemonade.ai onto it so you too can add a low parameter inferencing capability to the box?
Oh, you can't because of dependencies?
Here's how to fix it.
a) Add the missing repos
Code:
SSH in as root

Go to
/etc/apt/sources.list.d/debian.source
and change the 2 repos to include non-free

Add the new file

/etc/apt/sources.list.d/debian-backports.sources

with the following:

Types: deb deb-src
URIs: http://deb.debian.org/debian
Suites: trixie-backports
Components: main
Enabled: yes
Signed-By: /usr/share/keyrings/debian-archive-keyring.gpg

(do a save, and apt-get update - if you can't figure it out rename the 2 txt files attached here (by gettng rid of the .txt in the name, and then moving them to /etc/apt/sources.list.d/)
Code:
apt-get -y install libvulkan1 mesa-vulkan-drivers vulkan-tools
Code:
wget https://github.com/lemonade-sdk/lemonade/releases/latest/download/lemonade-server_11.5.2-debian13_amd64.deb
apt-get install ./lemonade-server_11.5.2-debian13_amd64.deb
apt --fix-broken install
systemctl enable --now lemond
Code:
wget https://github.com/Umio-Yasuno/amdgpu_top/releases/download/v0.11.5/amdgpu-top_0.11.5-1_amd64.deb
dpkg -i amdgpu-top_0.11.5-1_amd64.deb
Code:
lemonade config set host=0.0.0.0
service lemond restartThe HP t740 thin client
Is it useful in the context of a t740 (features a Ryzen embedded V1756B, which is the same as a Ryzen 5 2600H)?
Eeeeeh, marginally.
For example, if we download a small model (gemma-4-E2B-it) on a t740 (running proxmox 9.2) and run it with a context window of 32k, and by using the lemonade benchmark over 5 runs using this syntax:
Code:
root@pve2:~# LLM="Gemma-4-E2B-it-GGUF"
root@pve2:~# lemonade bench $LLM --backend vulkan --ctx-size 32768 --runs 5TTFT = Time to FIrst Token (in milliseconds, lower number is better)
TPS = Tokens per second (higher number is better)
16 is slower than realtime (usually 25) but it's somewhat tolerable.
Does context window size matter on this machine? Kinda. Here's lowering the ctx to 8k to compensate for less compute firepower...very slight improvement in TTFT time and slightly higher tokenization rate.
Are we sure it's working off the Radeon Vega 8 Embedded iGPU?
Yeah it is. What about a more frontier model like Qwen 3.8 with 4 billion parameters, q=8?
Eeeeeh, it's working but 7 tokens/sec isn't my idea of functional.
The HP t755 Elite thin client
What about the t755 (its successor), which has a Ryzen embedded V2546 (same as a Ryzen 5 4600H)? Can anything fun be done with it when it goes onto the secondary market one day?
Okay, well, it just so happens that I have a t755 as my production hypervisor, so I can do some quick testing.
Note that if you compare the numbers it's about 20% faster (from 16 to 20 tps) despite the fact that the Radeon Graphics 384SP iGPU on the t755 is roughly the same in terms of texture/FP performance as the Vega 8 Embedded iGPU on the t740 (the pixel rate is higher on the 384SP but not by much, roughly 15-20% higher)
So, eh, how do we know it's working?
What about the same trick with lowering ctx? Slight improvement but not by much.
What about Qwen 3.8? TTFT is significantly better but token-walking still suck.
20tps on Gemma-4 is almost about useful. Although I would be extremely cautious/skeptical about its factuality.
(at least 4 of those stations exist on another route coming out northwest of Tokyo, the train route is generally a south/southwest route, Kobe is west of Osaka on a completely different line, and both Atami and Odawara (major beachside resorts in the Kanto region) are both misreported as not being stops on the Tokaido Shinkansen. Hoooh boy...)
OFF-TOPIC
Comparison / e-Peen measurement with the Minisforum N5 Air, with or without AMD Radeon Pro V620 acceleration
In contrast, here's the Minisforum N5 Air (Ryzen 7 255H, same as a Ryzen 8845HS but with its useless XDNA NPU disabled) using its Radeon 780M iGPU on Debian 14 (should work on Debian 13). ROCm support for the 780M was added in Lemonade 11.6.
Note the much lower TTFT numbers due to the 780M having stronger compute overall (RDNA3.5 instead of Vega 2 GPU architecture).
If you have a strix Halo, the 780M is about 1/2 to 1/3 the computing firepower of your Radeon 8060S and with double 1/2 the RAM bandwidth, and based on benchmarks from Strix halo machines versus the 780M the numbers do jive with that difference.
Here's Gemma-4 E2B on the 780M, with Vulkan and ROCm respectivelyy...
And here's Qwen 3.8 with 4 billion parameters, condensed on quantization level 8, Vulkan and ROCm.
And here with its Radeon Pro V620 off an Oculink eGPU dock on Vulkan mode.
Gemma-4-E2B...Vulkan and ROCm
Qwen 3.8, Vulkan and ROCm
Yeah, TTFT is faster here but token walking is slower on ROCm.
Note that TTFT isn't much lower overall on the V620 versus the 780M, but the token walk rate is much better.
That hints to the RDNA3.5 compute units on the 780M being faster on a per-CU basis (but with less CUs than the V620 so it loses overall), but the higher token walk rate on the V620 is a direct correlation of its higher in-device memory bandwidth.
So, what does the V620 look like with its VRAM (32GB) maxed out and spilling over?
Here's Vulkan and ROCm on an 80B parameter, A3B model, which uses up ~30GB of VRAM out of the 48 needed (the rest will go to GTT/DDR5 system RAM).
And what about inferencing off the 780M using DDR5 system memory? Is the numbers that much worse?
Eh, I would say that paradoxically for certain tasks the 780M is not that far off from the V620...maybe about 1/3 slower...and for the code explain/debug tasks the 780M is actually almost-as-fast as the V620 and on Vulkan, even slightly faster on first token/prompt processing rate.
We'll need to see if the benchmark numbers jive with actual experiences.
Attachments
-
167 bytes Views: 0
-
473 bytes Views: 0
-
 580.3 KB Views: 0
-
 580.3 KB Views: 0
-
 451.2 KB Views: 0
Last edited: