
Ok, I just spent another half an hour beating my head against a wall or two... Because I'm not a docker expert, I was mostly just cutting and pasting a script. But I kept having file access issues in the debug or without debug. The volume part didn't look right to me, so I went back to docker wiki and looked up the format.. Still didn't get it right, but it's downloading "carbon-8b-q8" which it thinks is the best choice for my system. Have to wait and see if it finishes and runs a query, and check amdgpu_top to see what's happening.
Low power home AI for learning?
- Thread starter Greg_E
- Start date
Notice: Page may contain affiliate links for which we may earn a small commission through services like Amazon Affiliates or Skimlinks.
I haven't been following too closely along with your setup but if you have SELinux installed and set to Enforcing you may need aBecause I'm not a docker expert, I was mostly just cutting and pasting a script. But I kept having file access issues in the debug or without debug.
:z or :Z appended to the docker volume spec, that's my favorite under-documented mystery source of permissions errors.
I'll check that out as I play with this more. I also used :we to force read/write which might have been the ticket. I still can't find where it is storing the models, but it is some kind of persistent volume because the models were still present.
That above model was giving 0.7 t/s which is not going to be worth the electrons!
With the external e series card, I was getting very similar with gemma-3-12b-it. Shut things down, pulled the card and reset to igpu. Same request "help me write a windows group policy to remove copilot", this resulted in a 3.7 t/s which is probably as fast as I can go. About the same as cpu, but using only 70 watts (20 less than other testing). Amdgpu_top confirms 100% use in some areas while thinking.
I'll need to find optimizations or just put up with low end performance where it cooks along for hours doing simple tasks.
Well, I feel like a lot of the localAI documentation assumes some knowledge about how LLMs are supposed to work on your hardware, and that they really didn't bake in some tools that will make it easier to troubleshoot. Alright, guess I should probably write something that can help out...I figured it out over some Brubeck, coldbrew (Intenso Capri) and a cat on my sofa. It took maybe 10 minutes to get it to the point where I am okay with it, and almost an hour to compress that 10 minute experience into a forum entry…not because getting it to work is hard (it’s a cinch) but troubleshooting and benchmarking it properly requires more work than assumed.I'm thinking I need to test a different way too. I like the concept of localAI, but there is a new problem around every corner. I'm sure I can solve them all, and I'll be better off for solving it, but time is limited and I don't want to spend days of hours just getting to the point where I'm getting single digit tokens per second on really small models.
Also seems like this is going to need to move to a compose script since there seems to be a need for more config. I'll clean some things out and try again later, but it might be the last hurrah before I try a different solution like lemonaid with vulcan.
Last edited:
...not quite, since you are not running a docker container on proxmox, you are running an LXC container based on a converted docker image, and because of that, you lose some benefits of docker (the ability to switch/rebase OS/userland images while retaining the underlying data since docker has built-in support for that) while gaining some extra responsibilities (needing to explicitly specify how many CPU cores/how much RAM/having to explicitly tell the LXC engine to pass it the host resources), and you are still paying the (smaller but still present) overhead of running userspace virtualization. You also need to second guess whether whatever you run on the LXC container will be okay with whatever resources you pass it and whether it'll bump heads with any other things you are running on Proxmox itself. Fortunately shutting it down and fixing it is usually a cinch.It looks a lot easier for a container beginner to get running on proxmox, I should probably fire up docker desktop and see what it can show me.
For a more concrete example, let's take a look at the t755 thin client, which is my Proxmox server - it has both Lemonade-AI and an LXC image of local-ai running. We should probably pick a suitably small model like llama-3.2 1 Billion parameter (I pick that for a reason)
So do we know what the t755 is capable of with its Vega 6 iGPU on Vulkan mode via Lemonade-AI server's benchmark mode?
Yes...~40 t/sec isn't too bad.
So let's say that local-ai is running at full Vulkan mode. So can I expect 40+ t/sec on LocalAI?
2 questions - one on the Yugo and one about Uniqlo...
Not really...but that can be a bit subjective...that t755 Elite is also running other workloads, so maybe it eats into the performance margins. For the record Takashi Yanai was the founder of Uniqlo, and the first location is at central Hiroshima on June 1984, so the info from both LLMs are wrong but in different and interesting ways...note that he was not from Tokyo but Yamagauchi. He went to Waseda University in Tokyo but was considered mostly an outsider.
What about Lemonade AI itself? Same questions...
If I am reading the metrics off the logs I am pulling about 39 t/sec with prompt token rate of 160 or so (which is pretty okay).
What about the t740?
Well, let's see what Lemonade-Server thinks it's capable of.
Well, it can do about 30 t/sec instead of 40 t/sec. What about localAI?
Yeah, it can pull about 26-30 t/sec...which is roughly where I expect it to be. What about Lemonade AI?
Yeah, it's about where it should be. So yeah, maybe it's picking the right LLM to run it.
That being said, LocalAI does not have built-in benchmarking functionality, and therefore it's difficult to use it to gauge performance effectively. When I was trying to benchmark the systems I tried localScore, which bundled the LLM and its binaries/sharlibs into a single app. For the "tiny version" the bundled underlying LLM is Llama 3.2 1B Instruct - Q4_K (oh what a coincidence, same LLM that I ran on lemonade_ai and on localLLM...it's almost like I planned it)
So how did the t755 Elite fare with the localScore suite?
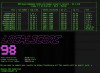
That's not bad...per-se. What about the t740?
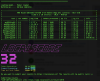
eeeeeh. On closer examination of the results...it's CPU based. What happened to GPU support?
Eh, looks like the LocalScore benchmarking suite only supports CUDA (nVidia) and ROCm (selected AMD)...but not Vulkan.
So it looks like native Vulkan support is not a thing, How does it handle a more modern iGPU (like the 780M or the Radeon Pro V620)?
Well, ROCm will work definitely for the V620, but for the 780M I am not so sure...
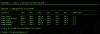
Edit: Hey, looks like lemonade 11.6 fixed support for ROCm in the 780M (and other hardware) recently. What about Vulkan?
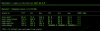
Eeeeeh, okay. So tokenwalking in the 70s in ROCm, and 90s in Vulkan. What about using LocalScore?
Eh, why is it seemingly using an old ROCm build (6.4) to pretend to be CUDA...?
Oh. localScore hasn’t showed any updates since last year.
How did the 780M fare?
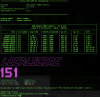
...not great. And somehow it scored only 1/3 better than the t755's CPU-only mode despite being nearly 4x better in prompt processing with some oddly low tokenwalking scores. How about using the CPU?
Does that jive with lemonade's benching utilities?
Around 60s to 70s.
What about the V620?
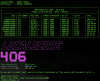
Okay, the prompt processing is much higher but how the hell is the token generation numbers so slow despite the much higher VRAM bandwidth?
What was it supposed to be? Let's see...
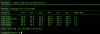
....what about the Vulkan backend?
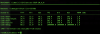
Like I've said before...for AMD GPUs, Vulkan gives you worse prompt processing, but better token traversal compared to ROCm
Well, so what can I say? The fact that the localscore suite is not up to date skewed the results significantly if it's using an old ROCm binary to run CUDA benchmarking code.
So, is there a sizable penalty on running an LXC? Yeah, less than 2%, I would say, at least from the perspective of CPU based inferencing.
Here's the t755 running the localscore suite on CPU mode.
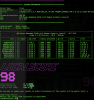
(that's run within the LocalAI LXC on the t755)
What about the t740 running localscore within an LXC container?
Yeah, I'll say that the performance penalty is there but not nearly as severe. So note that in addition to the pitfalls of LXC/Docker, you'll still need to keep the software updated and to ensure that the hardware is working properly. The fact that localscore hasn’t been updated for a while didn’t help.
Last edited:
I'll have to look at some other models and see how they perform. I may also move from openSUSE Leap to Leap micro and maybe try localAI in podman and see if there is a difference. I'm also still thinking about swapping to 64GB of ram to see what happens, if anything it brings bigger models to the table, looks like I can get about 1/3 of system ram so more might be better.
And maybe I should get an external pcie box to frankenPC this thing with a v620 or two. 8 lanes from the slot, and I could drive a second card at 4 lanes from the nvme slot if it would help. A box with a switch chip and two x16 slots would be fun. Maybe a pcie thunderbolt card to enclosure? Might be a better way?
And maybe I should get an external pcie box to frankenPC this thing with a v620 or two. 8 lanes from the slot, and I could drive a second card at 4 lanes from the nvme slot if it would help. A box with a switch chip and two x16 slots would be fun. Maybe a pcie thunderbolt card to enclosure? Might be a better way?
Eh, the underlying OS rarely has any influence on how things run, unless the OS makes it easier to install updated AMD RADV or ROCm drivers...which won't for OpenSuSE (AMD itself gravitate towards Fedora or Ubuntu/Debian for the most part), and as for RAM....eeeh, it depends on how much you are passing into localAI. Adding RAM really just allow you to use more for running bigger, more complex LLMs...it won't help make things run better, since it's still the same CPU or GPU with the same compute running on the same pool of system RAM on the same underlying tech. In fact, running more complex LLMs will simply make the LLM less performant if you are hardware constrained.I'll have to look at some other models and see how they perform. I may also move from openSUSE Leap to Leap micro and maybe try localAI in podman and see if there is a difference. I'm also still thinking about swapping to 64GB of ram to see what happens, if anything it brings bigger models to the table, looks like I can get about 1/3 of system ram so more might be better.
And maybe I should get an external pcie box to frankenPC this thing with a v620 or two. 8 lanes from the slot, and I could drive a second card at 4 lanes from the nvme slot if it would help. A box with a switch chip and two x16 slots would be fun. Maybe a pcie thunderbolt card to enclosure? Might be a better way?
As for adding an external PCIe thing to run the V620 or the V340L on the t740 or the t755? Unless something changes wth the BIOS feature-set? Don't bet on it. I tried using a PCIe to Oculink adapter (20 bucks on Amazon) to connect the t740 or the t755 to the Minisforum DEG01 dock (running the V620), and either it just sits there and does nothing (no PCIe device detected)...or they just fails to post. My guess is that both BIOS does not do BAR resizing so it basically won't start with the card turned on. The same will likely apply on the Intel B50/60/70 series Battlemage cards.
You'll still need a dock (110 USD), a power supply for the dock (85 USD), and in the case of the V620, a blower for it (30 USD). Even if it’s just a PCIe flex-ribbon to the V620 it still doesn’t lift the requirement for a separate power supply and the blower, and you’ll have to figure out a way to toggle the card power on.
If you want to go with Thunderbolt you'll need a TB4 to PCIe card (110 or so), a TB4 dock (anywhere from 120 to 200), a power supply (85+ for a decent one), and then the card+blower. And whether it works or not is still a major unknown.
Edit: confirmed that BAR resizing (requirement for AMD Radeon Pro cards) will not work for both the t740 and the t755 Elite. Can't wait to see if it also fails for the Wyse 5070 "fat".
Last edited:
Thanks, always good advice.
Still having some storage issue on this little machine, still some work to be done. I did have a task for it today, and as far as I know, that answer is not only correct, but it explained why I needed to take some of these steps. I'll probably just run what I have until a deal on something better pops up, or until I can't do something I really want to do.
The reason to move to Leap Micro is that I need to move several other things off of a full desktop debian, and need to be deeper into the SUSE ecosystem. Harvester and Kubernetes are going to be running a openSUSE micro or Elemental special micro, getting a firm grip on both is a goal right now.