How is everyone setting up Local AI in thier home labs? Idea thread.

Notice: Page may contain affiliate links for which we may earn a small commission through services like Amazon Affiliates or Skimlinks.

anakronox

Member
Mar 17, 2025
32
8
8
It wasn't a cheap solution but I added an Asus GX10 (DGX Spark variant) and it's been awesome. Huge 128GB of VRAM lets me run Qwen 3.6 35B-A3B Q5 with Vision mod, ComfyUI, a Tdarr node with 2 possible concurrent transcodes, an Immich ML container, and I've still got roughly half the VRAM leftover for other models to play with. Is it the fastest? Nah, but it's already let me take the Arc GPU's out of my MS-01 Proxmox nodes and throw in a couple of 25Gbps NIC's. The software stack on the GB10 platform is changing weekly and seems to be getting better. I did have to build custom Docker containers for Immich ML and some other things I'm playing with, simply because ARM support isn't universal.

It's been a fun learning experience to see how to build out useful AI at home. Next step is seeing if it can automate some smart home devices.
 

marcoi

Well-Known Member
Apr 6, 2013
1,724
418
83
Gotha Florida
So its been a while since i updated my setup, so here is how i have my setup now on the n5pro.

Hardware:
  • N5pro NAS with 96GB ram
  • Currently have AMD GPU set to 2gb ram - using for monitor only.
  • I have deg1 oculink doc with intel arc b70 video card connected.

OS/Software:
  • Windows 11 Pro - I decided to use windows as it is easier to Remote into vs Ubuntu. I also think the hardware drivers are updated faster in windows.
  • I compiled llama.cpp with intel sync for the B70 card ( huge gains over lm studio)
  • I am using Lemonaid server with FLM to run two models on the NPU
  • I am using Virtualbox running Ubuntu 26 VMS.
Setup/Design:
  • So I have windows 11 as the OS, again easier to manage/backup and remote into.
  • I am running llama.cpp sync build for intel arc card with Qwen3.6-35B-A3B-Q4_K_M.gguf
    • This was a pita to get built but it is worth the effort. Tokens per sec with Qwen model is consistently around 75. Prompt tokens range around 400-600.
  • I am using Virtualbox to run Ubuntu 26 VMs to run agents.
    • Currently I have hermes agent and second vm for openclaw.
      • I am mostly focusing on hermes.
      • I use clone and snaps as backup method for when i am playing with agents and changes.
  • I have hermes setup to run on local LLM it connects to llama.cpp.
    • I setup a local hosted honcho on the VM under dockers.
      • It connects to lemonaid server NPU for LLMs.
        • Currently working on getting it running correctly.
    • I setup telegram bots to work with hermes gateways
      • A default gateway is used for local terminal in VM
      • Assistant gateway bot for doing things around the house, like HA config
      • Dev gateway bot to do dev projects.
    • Each hermes profile above has its own personality/soul.
I am probably forgetting things, but this is an overview of what i am doing.

Next on the todo list:
  • I am working on getting hermes setup with email so it can start emailing me reports and results.
  • getting honcho to work with local setup.
 

anakronox

Member
Mar 17, 2025
32
8
8
MTP models have been released, you should check it out, unsloth publishing new quants right now.
NVFP4 quants for Qwen 3.6 35B A3B with MTP are finally out and I'm testing them now vs. Q5. So far they're just as accurate if not a little more so with structured file formats like YAML and writing Python scripts. At least on the GB10 hardware it's also improved token generation from ~40 to ~50 average tps. Not bad.
 

marcoi

Well-Known Member
Apr 6, 2013
1,724
418
83
Gotha Florida
latest update.
I been fine tuning the setup.

For eGPU b70
  • running llama.cpp build with sync enabled.
  • 3 parallel one for each hermes agent

Code:
llama-server.exe -m "M:\models\lmstudio-community\Qwen3.6-35B-A3B-GGUF\Qwen3.6-35B-A3B-Q4_K_M.gguf" -c 196608 --parallel 3 -ngl 99 --host 0.0.0.0 --port 1234 --metrics --cache-type-k q8_0 --cache-type-v q4_0 --flash-attn on --context-shift -b 4096 -t 4 -tb 12 --temp 0.3 --top-p 1.0 --min-p 0.05
Code:
# HELP llamacpp:prompt_tokens_total Number of prompt tokens processed.[/INDENT]
[INDENT=2]# TYPE llamacpp:prompt_tokens_total counter[/INDENT]
[INDENT=2]llamacpp:prompt_tokens_total 75284[/INDENT]
[INDENT=2]# HELP llamacpp:prompt_seconds_total Prompt process time[/INDENT]
[INDENT=2]# TYPE llamacpp:prompt_seconds_total counter[/INDENT]
[INDENT=2]llamacpp:prompt_seconds_total 250.578[/INDENT]
[INDENT=2]# HELP llamacpp:tokens_predicted_total Number of generation tokens processed.[/INDENT]
[INDENT=2]# TYPE llamacpp:tokens_predicted_total counter[/INDENT]
[INDENT=2]llamacpp:tokens_predicted_total 3385[/INDENT]
[INDENT=2]# HELP llamacpp:tokens_predicted_seconds_total Predict process time[/INDENT]
[INDENT=2]# TYPE llamacpp:tokens_predicted_seconds_total counter[/INDENT]
[INDENT=2]llamacpp:tokens_predicted_seconds_total 118.641[/INDENT]
[INDENT=2]# HELP llamacpp:n_decode_total Total number of llama_decode() calls[/INDENT]
[INDENT=2]# TYPE llamacpp:n_decode_total counter[/INDENT]
[INDENT=2]llamacpp:n_decode_total 3164[/INDENT]
[INDENT=2]# HELP llamacpp:n_tokens_max Largest observed n_tokens.[/INDENT]
[INDENT=2]# TYPE llamacpp:n_tokens_max counter[/INDENT]
[INDENT=2]llamacpp:n_tokens_max 25468[/INDENT]
[INDENT=2]# HELP llamacpp:prompt_tokens_seconds Average prompt throughput in tokens/s.[/INDENT]
[INDENT=2]# TYPE llamacpp:prompt_tokens_seconds gauge[/INDENT]
[INDENT=2]llamacpp:prompt_tokens_seconds 300.441[/INDENT]
[INDENT=2]# HELP llamacpp:predicted_tokens_seconds Average generation throughput in tokens/s.[/INDENT]
[INDENT=2]# TYPE llamacpp:predicted_tokens_seconds gauge[/INDENT]
[INDENT=2]llamacpp:predicted_tokens_seconds 28.5315[/INDENT]
[INDENT=2]# HELP llamacpp:requests_processing Number of requests processing.[/INDENT]
[INDENT=2]# TYPE llamacpp:requests_processing gauge[/INDENT]
[INDENT=2]llamacpp:requests_processing 0[/INDENT]
[INDENT=2]# HELP llamacpp:requests_deferred Number of requests deferred.[/INDENT]
[INDENT=2]# TYPE llamacpp:requests_deferred gauge[/INDENT]
[INDENT=2]llamacpp:requests_deferred 0[/INDENT]
[INDENT=2]# HELP llamacpp:n_busy_slots_per_decode Average number of busy slots per llama_decode() call[/INDENT]
[INDENT=2]# TYPE llamacpp:n_busy_slots_per_decode gauge[/INDENT]
[INDENT=2]llamacpp:n_busy_slots_per_decode 1.09355

For NPU
  • Used for local running honcho memory for hermes
  • Lemonaid server running FLM
  • gwen3.5-2b and embeded-gemma
Code:
2026-06-24 17:16:14.342 [Info] (Telemetry) === Telemetry ===[/INDENT]
[INDENT=2]2026-06-24 17:16:14.342 [Info] (Telemetry) Input tokens:  5869[/INDENT]
[INDENT=2]2026-06-24 17:16:14.342 [Info] (Telemetry) Output tokens: 299[/INDENT]
[INDENT=2]2026-06-24 17:16:14.342 [Info] (Telemetry) TTFT (s):      5.74[/INDENT]
[INDENT=2]2026-06-24 17:16:14.342 [Info] (Telemetry) TPS:           22.14
For iGPU
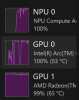
  • LM studio finally able to see both cards. So I assigned only the igpu and have it running gpt-oss-20b
  • I have igpu memory set to use 16GB ram.
  • Using it for context compression with hermes agent.
  • Still a work in progress.

1782336117443.png
 
  • Like
Reactions: cesmith9999

unwind-protect

Well-Known Member
Mar 7, 2016
621
252
63
Boston
Today's Apple price increase threw a wrench into my plan to use a 128 GB Macbook as a LLM runner. I guess Strix Halo it is.
 

mattventura

Well-Known Member
Nov 9, 2022
794
442
63
Are there good coding setups that have good IDE integration? That's the one thing I've been missing from local models. I've been considering a couple MI50 or MI60s but waiting for the software/integration side of things to get a little better.
 

Klee

Well-Known Member
Jun 2, 2016
1,302
411
83
I have only been messing with AI for about a month.

I wanted to build a "new" pc for months, main pc is a Asrock B650E Taichi, Ryzen 7600 and 32 gigd of DDR5 -6000, but since everything is so expensive and since I decided to go in a different direction with my ProMox build I decided to use the motherboard from that to build me a "new" pc that actually feels like a new one.

So I picked my most powerful hardware I had on hand and threw it into a new case, originally I had zero interest in AI but after I built the pc it turned into sort of a side quest.


Asrock Rack EP2C621D12 WS motherboard.
Two Xeon Gold 6148 cpu's.
192 gigs of ram,.
Trusty EVGA RTX 3090 Ti ftw3 gpu.
Intel 2 tb nvme drive.
EVGA 1600 watt power supply.
New: Fans.
2 Asetek AIO cpu coolers, with bquiet pressure optimized fans.
New: Thermaltake View 600 TG case in Purple.
Asus Xonar dx 7.1 pci-e sound card
New: Cheap usb-c pcie card to connect to the front of the case.
New: Billet aluminum gpu support, its REALLY nice.

Ubuntu 24.04.4 Desktop.

Only cost me about $260.00 not including the hardware I already had.

Like I said I had plans to just run it as my main pc for a while but I had a video on youtube pop up about Hermes Agent and it looked interesting so I installed Ollama and Hermes 0.14.0.

I wanted to run a local AI model so I ran qwen3.5:27b at first.

Made a simple html game, not really much but hey its my first game I created.

I decided when I was goofing off to create a AI image of an old black & white photograph of Bigfoot in the Pacific north west, the Bigfoot looked totally fake but the background landscape looked really nice so that led me into a landscape pic marathon.


It ran amazingly well, I started to create images in the style of 1850's to 1880's black & white pictures since as a teen in the 1970's I was big into b&w photography and developed and printed them myself.

Some AI images I created in the style of 1850's daguerreotype photographs:


Then after chatting with Hermes "we" decided to upgrade to Ubuntu Server 26.04, qwen3.6:27b and a newer version of Ollama.

That was a HUGE mistake and I should have left it alone since everything ran so well.

After the software "upgrade's" nothing but issues, truncate errors, out of memory errors, and on and on for several weeks.

Narrowed the issue down to the version of Ollama and tried ALL the fixes I found online then got frustrated and decided to move on.

Now I am back on Ubuntu 24.04.4 desktop running Llama.cpp instead of Ollama, Hermes Agent 0.17.0 all on bare metal, not in a VM or Docker and its running MUCH better with zero errors or issues so far.

Currently running ornith-1.0-9b-bf16.gguf with Hermes interfacing with Comfy-UI.

I had no plans to create landscape pics but I am having a bunch of fun doing it.

Best picture so far that is not a landscape, remember I only have a couple of weeks using any AI, so I think this turned out really well.

A Victorian style portrait of a woman that looks really nice and with normal hands AND with the correct number of fingers. :cool:


That's what I am doing so far, but like I said this is very new to me and I will try new things.

The only other thing I have done it enabled persistence and limit the RTX 3090 ti to 350 watts instead of the default 450 watts at boot as to take it easy on the 3090 and not abuse it too much.

Edit to add, I also did some mid 20th century style color pics.

 
Last edited:

Klee

Well-Known Member
Jun 2, 2016
1,302
411
83
How is everyone setting up image creation process. Apps/LLM/etc? I been playing with amuse that amd is promoting. but wanted to know how to setup a server so i can call the backend via another app or agent.
I just told Hermes that I wanted to create some images and after "he" questioned me about exactly what I wanted to do I let "him" download, install and configure everything.

That might have been a little on the dangerous side especially when I gave him the sudo password, well "he" did tell me it would not be saved, but it turned out well enough. LOL

Edit to add: It's a dedicated AI build now with zero important or personal info on the machine, all I do is SSH into it and run Hermes in a terminal.
 
Last edited:
  • Like
Reactions: marcoi

bayleyw

Active Member
Jan 8, 2014
361
135
43
Adding one more to my zoo:

  • 16x V100 32GB SXM2 (two nodes), 2026: Volta has aged well. This eight-year-old monstrosity runs GLM-5.1 out to the full 202K token context (and should run GLM-5.2 out to 250K+ as well, but I haven't downloaded the weights yet). With many custom kernels (I had to write an SM70 DSA implementation, a fast indexer, and implement fp8 KV cache and fp8 attention/dense/shared experts as well as do a ton of micro-optimization) it gets 1900 tokens / sec prefill at 200K context, 25 tokens / sec decode at 16K context, and most important, nearly flat performance from 2K to 200K in both prefill and decode courtesy of linear attention. It also finally beats the rich kids with their $16K stacks of DGX Sparks (they have to prune the model and turn on MTP to get 25 tokens / sec decode) and absolutely trashes a 512 GB Mac Studio, which gets 10 tokens / sec decode and what I imagine is double-digit prefill at long context courtesy of the shitfest that is llama.cpp. In case you are wondering, fp8 KV/attention should be safe on this model - it is what the official Zai API uses.

The economics on this one are interesting. It can prefill almost seven million tokens per hour, which is $10 at current API prices, but can only generate 39 cents of tokens per hour servicing a single stream. My guess is serving a single user it does about $2 of work per hour, so at current hardware pricing it would take about 8 months of 24/7 usage to break even.

The model is quite good. GLM5 is the only open source model I would consider for serious work and it is definitely better than Sonnet. It also has a nice clean reasoning trace which makes it good at easier tasks - Opus tends to overthink on straightforward tasks. Zai is a really nice company too - I know their US sales lead and the team seems to be committed to building good models and competitive products.

Should you actually build this? I am not sure. GLM5 is not Opus and never will be, because Opus keeps getting better and now we have Fable. If you just chat, you can get virtually unlimited Sonnet for $20 a month so you'll be dead by the time the cluster pays itself off. If you have a real reason to self-host (legal? medical? but would I trust my life to GLM-5.1-AWQ running on some used computers from 2018?) it kind of makes sense, but you could also just pay someone $100K for an 8x RTX Pro 6000 system and expense it.
 
Last edited:

fasting

New Member
Jan 24, 2017
6
4
3
39
I started playing with local LLM recently and ended up running OpenCode together with Ollama for my personal coding tasks. In order to get usable results I am using model qwen3.6. Unfortunately I don't have the proper hardware for it, resulting in this:

Bash:
$ ollama ps
NAME           ID              SIZE     PROCESSOR    CONTEXT    UNTIL             
qwen3.6:27b    a50eda8ed977    35 GB    100% CPU     262144     4 minutes from now

$ free -h
               total        used        free      shared  buff/cache   available
Mem:            30Gi        29Gi       339Mi       674Mi       1.2Gi       374Mi
Swap:           30Gi        15Gi        15Gi
oc-time.png

Probably at least 20+ years since I actually had to use the swap space.

Still though, things work and now I need to find a GPU for this. Too bad everything is so damn expensive. Hard to justify the money for pet projects. (Yes I know about cloud-based solutions, but I prefer to run things locally.)
 

marcoi

Well-Known Member
Apr 6, 2013
1,724
418
83
Gotha Florida
I started playing with local LLM recently and ended up running OpenCode together with Ollama for my personal coding tasks. In order to get usable results I am using model qwen3.6. Unfortunately I don't have the proper hardware for it, resulting in this:

Bash:
$ ollama ps
NAME           ID              SIZE     PROCESSOR    CONTEXT    UNTIL            
qwen3.6:27b    a50eda8ed977    35 GB    100% CPU     262144     4 minutes from now

$ free -h
               total        used        free      shared  buff/cache   available
Mem:            30Gi        29Gi       339Mi       674Mi       1.2Gi       374Mi
Swap:           30Gi        15Gi        15Gi
View attachment 49588

Probably at least 20+ years since I actually had to use the swap space.

Still though, things work and now I need to find a GPU for this. Too bad everything is so damn expensive. Hard to justify the money for pet projects. (Yes I know about cloud-based solutions, but I prefer to run things locally.)
seems like a used AMD Radeon Pro V620 32 gb can be had for 400-500 range if it fits your budget/components. I was considering getting one to play with but my current setup seems to be dialed in enough where im happy enough with it.
 

WANg

Well-Known Member
Jun 10, 2018
1,564
1,194
113
48
New York, NY
seems like a used AMD Radeon Pro V620 32 gb can be had for 400-500 range if it fits your budget/components. I was considering getting one to play with but my current setup seems to be dialed in enough where im happy enough with it.
So, how does one get more intelligence in the home lab?

SIMPLE - YOU GET MARRIED AND YOUR WIFE TAKES OVER. THE BARELY TOILET TRAINED NEANDERTHAL IS NO LONGER IN CHARGE
(Just kidding)

Well, I have a very similar setup to yours (Minisforum N5 Air instead of N5 Pro), and I chose the Radeon V620 on a Minisforum DEG01 instead of the RTX4060 mostly because it's cheap (and immediately available), has 32GB of VRAM, runs (somewhat) like an RTX3070 with decent numbers, and since it's on an Oculink dock, it can be powered off (during a reboot) independently to save me power and noise in my relatively small NYC pre-war apartment. That 41 cents/Kwh ConEd bill sure doesn't look all that appealing after the summer heat wave, and I am not running my GPU all the time unless a) I am not home or b) my wife won't kill me for the noise.

Why the N5 Air? Because it was 300 dollars cheaper than the Pro, and at the time I needed a cheap(ish) NAS enclosure to replace my supposedly dying N40L with some decent performance numbers and room to grow. While I have some underutilized DDR5 SODIMMs from before the price increases, I don't have any ECC DDR5 SODIMMs which will justify the jump to a Strix Point based AI9 HX370, although to be honest, I don't think it's needed.
I had multiple NAS crashes in the past due to the power supply dying, but none due to RAM errors, and that's with 8 years of using plain jane desktop DDR3 on my HP Microserver G7 N40L. The N40L only got a pair of 8GB ECC DDR3 DIMMs in 2021-ish after I got sick and tired of the RAM playing boot-up roulette with me, sometimes coming up with 8GB or 16GB on the RAM count - but honestly, I don't ever see parity error corrections on the system log, but I did see plenty of device brown-out kernel panics thanks to the PSU acting funny.

First, some photos!
(yeah, the big Lego plane collection just keep growing)...

Okay, so here's what it usually looks like - note the Cobalt Qube3 Pro on top of the Minisforum - a consumer level AMD powered NAS from 20 years ago on top of a modern one. The Radeon Pro V620 is on the DEG01 dock with the 3D printed Instinct MI50 shroud + blower, and there is a BeQuiet 13M PSU powering it up. Having a Japanese F-4EJ Kai (on its Lego stand off the DEG01/BeQuiet 13M) and a Ukrainian Su-24 (on top of the Qube 3) does help set the scene of much noise and excitement.
1784831714584.png

It's a bog standard, run of the mill Minisforum NAS enclosure and it is doing yeoman duty running LLMs...
1784831803804.png
So here's what the DEG01 looked like before it became the racking solution for my planes...
1784833677860.png

Note that some cable management was done just to keep things tidy...and as my wife said, "are you sure that's not penisforum"?

How was it controlled, power-wise?

Z-Wave power plugs, one for the N5 Air and one for the DEG01.

The not-really-NAS is outfitted with a Kioxia XG8-512GB NVMe SSD and 2x64GB Crucial DDR5-5600 SODIMMs..and it uses less power than the HP t755 compute node (the N5 Air pulls 14-16W idle, about 83 when maxed - this compares to the t755 (which idles at 25 with a pair of 32GB SODIMMs, a Mellanox MCX354A ConnectX3-VPI and a single 512GB Crucial P3 NVMe SSD). The V620 is on "full send" at the moment, so to speak, eating up ~320 Watts digesting through yet another one of my less than brilliant lines of questioning when I kept asking different LLMs for cat food recipes featuring roasted garlic, or plan summer clambake recipes for the local Yeshiva, or trying to convince the LLM that Gil Hodges played Mr. Spock on Star Trek. I am polishing my LLM poisoning techniques here.

DEG01 idles at ~30-50 watts when not in use.
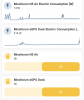
1784833754778.png

The concern here is that the V620 consumes more power than the rest of the rack devices combined, which can set off the overload alarm on the APC BE600M1 UPS.
1784834037188.png

So, is there a difference between when the DEG01 dock is powered up and not?

Yeah, one sounds like an office, the other sounds like an office with someone vacuuming at the end of the day...

Off ~
1784834163093.png

~ On

1784834228474.png

So, how do we switch from iGPU to V620 and vice versa? Simple - ssh in, send it a reboot command, count to 7, and then toggle the Z-Wave power plug for the eGPU dock on...or off. When the hardware boots up it'll either detect the GPU as being attached or not...and you can check accordingly usng amdgpu_top. If the V620 shows up you'll see both it and the 780M on the device list. Otherwise it'll just show the 780M.

Okay. Enough pretty pictures. What about the solid numbers?

Okay, what is in my N5 Air?

Hardware-wise?
Ryzen 7 255H (basically an AMD Zen4 HawkPoint based Ryzen 7 8845H but with its 4 TOPS XDNA1 NPU disabled), 128GB of RAM, a single 512GB SSD, DEG01 GPU dock connected via Oculink, BeQuiet PurePower 13M modular power supply,AMD Radeon Pro V620 + MI50 blower.

Software-wise?
Debian 14/Forky, , ROCm 7.2.4 with Lemonade AI Server running the LLMs via llama.cpp and etc via backend modules (subsequently upgraded to 7.14).

How useful is XDNA1 (the neural engine on the Zen4 based Phoenix/HawkPoint APUs ) and why didn't I care about it being missing on the Ryzen 7 255H all that much?

Well, it’s not sour grapes (I have a Framework 13 with a Phoenix based Ryzen 7 7840U, so I do have access to one) - but It’s essentially a waste of silicon as things stand as of Q3 ‘26. XDNA1 is not nearly as heavily promoted or focused by devs as XDNA2 (the neural engine on the Zen5 based Strix Point/Strix Halo APUs like the one on the N5 Pro).
If AMD struggles to make XDNA2 useful to LLM, XDNA1 is that plus much weaker and even less popular. It's basically the sugar-free penis flavored lollipop of the NPU world. The Radeon i780M iGPU found on Zen4 APUs on the other hand? That gives you decent (not exciting or invigorating) performance for small LLMs, but just keep in mind that your RAM bandwidth is ~130MB/sec (around that for the N5 Pro), compared to ~250 for Strix Halo or the 200 on an Apple M1 Pro or the 300 on an M5 Pro, so while your prompt processing rate is “okay/so-so”, your sustained token traversal rates would not be great. Maybe 30-ish sustained?

Is resizable BAR turned on for better GPU throughput (keep in mind that the dock is only PCIe 4.0x4)?

Code:
root@LocalCabeza:~# lspci -v | grep -i V620
pcilib: Error reading /sys/bus/pci/devices/0000:00:08.3/label: Operation not permitted
03:00.0 Display controller: Advanced Micro Devices, Inc. [AMD/ATI] Navi 21 [Radeon Pro V620]
root@LocalCabeza:~# lspci -v -s:03:00 | grep -i size\=
        Memory at 2800000000 (64-bit, prefetchable) [size=32G]
        Memory at 27ffe00000 (64-bit, prefetchable) [size=2M]
        Memory at fa000000 (32-bit, non-prefetchable) [size=512K]
        Expansion ROM at fa080000 [disabled] [size=128K]
Well, that 32GB memory region will say "yes, it is". It's normally 256MB.

What are we using on the machine for inferencing?

Code:
root@LocalCabeza:~# amd-smi
+------------------------------------------------------------------------------+
| AMD-SMI 26.2.2+97f5574fe2    amdgpu version: Linuxver ROCm version: 7.2.4    |
| VBIOS version: 606253                                                        |
| Platform: Linux Baremetal                                                    |
|-------------------------------------+----------------------------------------|
| BDF                        GPU-Name | Mem-Uti   Temp   UEC       Power-Usage |
| GPU  HIP-ID  OAM-ID  Partition-Mode | GFX-Uti    Fan               Mem-Usage |
|=====================================+========================================|
| 0000:03:00.0    AMD Radeon PRO V620 | 0 %      32 °C   0            10/250 W |
|   0       0     N/A             N/A | 0 %        N/A             16/30704 MB |
|-------------------------------------+----------------------------------------|
| 0000:c8:00.0    AMD Radeon Graphics | N/A        N/A   0                 N/A |
|   1       1     N/A             N/A | N/A        N/A             117/2048 MB |
+-------------------------------------+----------------------------------------+
+------------------------------------------------------------------------------+
| Processes:                                                                   |
|  GPU        PID  Process Name          GTT_MEM  VRAM_MEM  MEM_USAGE     CU % |
|==============================================================================|
|  No running processes found                                                  |
+------------------------------------------------------------------------------+
And now, here's a bunch of numbers for your amusement and e-peen length/girth comparison, gathered via Lemonade-eval.
Prompt processing to 512 tokens and token generation to 128 tokens are done at 5 runs each and averaged out, here's the rough testing methodology.

TESTING METHODOLOGY

Code:
time lemonade-eval -i $model load --server-url http://localhost:13305 bench -p 512 --output-tokens 128 --iterations 5 | grep real

(and then divide the number of seconds by 5, obvs - this is used for power usage testing since I'll need an ability to compare time savings persus wattage consumption to derive a rough estimate of efficiency)
There's one set for V620 on ROCm, one for V620 on Vulkan and one for the 780M iGPU for both ROCm and Vulkan. ROCm is usually slightly slower than Vulkan, but I usually stick with Vulkan for compatibility purposes. ROCm is usually fairly solid on the V620, but
on the Radeon 780M/GFX1103, it had to wait for the client apps (lemonade-ai) to progress past v11.6 and above. The situation for the Ryzen 9 AI370 and it's Radeon 890M/gfx1150 iGPU is about the same That being said, The 780M certainly punches above its weight simply because RDNA3 is a solid improvement over the RDNA2, and on a per-watt basis it delivers okay numbers. The 890M in the N5 Pro should yield 10-15% better numbers versus the 780M provided that you feed it with similar DDR5-5600 memory (the AI370 can do LPDDR5X-8500, but this is a socketed machine and the socket isn't LPCAMM2).

PERFORMANCE (FOR AMUSEMENT PURPOSES ONLY, CONSUME WITH GRAINS OF PINK HIMALAYAN SALT)

All tests are run with the context window (ctx) set to 32768, BTW.

AI ModelV620 ROCm pp512V620 ROCm tg128V620 Vulkan pp512V620 Vulkan tg128Radeon 780M ROCm pp512Radeon 780M ROCm tg128Radeon 780M Vulkan pp512Radeon 780M Vulkan tg128
Gemma-4-E2B-it-GGUF
3393.75​
123.5​
3581.18​
138.73​
879.42​
40.48​
965.96​
44​
Gemma-4-E4B-it-GGUF
1869.73​
76.4​
1936.78​
82.56​
451.84​
21.32​
490.24​
23.6​
Gemma-4-12B-it-GGUF
784.4​
41.27​
762.89​
43.5​
194.63​
9.22​
208.85​
10.16​
Gemma-4-12B-it-MTP-GGUF
761.71​
70.97​
753.3​
69.27​
193.79​
11.29​
209.88​
18.85​
Ministral-3-3B-Instruct-2512-GGUF
3065.78​
116​
2952.41​
126.61​
777.84​
30.03​
808.45​
33.74​
Nemotron-3-Nano-30B-A3B-GGUF
1764.95​
97.32​
1527.42​
105.75​
359.37​
21.02​
379.8​
26.5​
Qwen3.6-27B-MTP-GGUF
380.607​
30.43​
395.73​
38.92​
93.66​
6.22​
90.26​
9.15​
Qwen3.6-35B-A3B-GGUF-Q4_K_M
1576.46​
80.1​
1633.8​
97.6​
327.52​
26.47​
365.8​
22.27​
Qwen3.6-35B-A3B-MTP-GGUF
1656.38​
76.48​
1541.15​
103.07​
349.82​
31.12​
360.12​
29.95​
Qwen3-Coder-Next-REAM-i1-GGUF-Q3_K_M
1213.5​
62.5​
1274.67​
79.76​
258.57​
23.13​
273.55​
25.24​
gpt-oss-20b-mxfp4-GGUF
1873.97​
106.3​
1630.48​
120.5​
383.53​
25.36​
339.71​
28.02​

Note that the current set of numbers have the Gemma-4 35B LLMs removed due to...well, I ran out of storage and had to nuke the gguf files, and plus it wasn't too great in terms of performance.
I expected the tg128 numbers (original) to stay roughly the same as the tg512 numbers. I expect the tokenization rates to stay pretty consistent as the numbers of tokens increases and it converges to a limit. If you have a car run the Nurburgring for 5 laps versus 15 laps, if you have a good tamed racing driver with a consistent path, the lap times between 5 and 15 across multiple race day sessions will eventually converge to roughly similar numbers.

As for prompt tokenizing, there is probably something like a curve with a steep rise and a gentle slope downwards.
To visualize it, imagine pp128 and pp512 as like having your car run from 0 to 30 versus 0 to 60 and looking at its laptime.
Some cars (like the Citroen 2CV or the VW Beetle) is known for high acceleration from 0 to 30 but runs out of steam after about 35 mph, while others (family sedans) are optimized for cruising at 60, while others (like a BMW i8 or Corvette C8) can blow easily past 120. In the original pp128 tests we are only asking the hardware to evaluate the full power of the extra compute units, but in most cases the full firepower were not bought up before the prompt processing tokens were already done - by allocating extra prompt processing tokens from 128 to 512 we are actually making a more meaningful test.

The V620 is not a speed demon nVidia RTX Blackwell - in fact, I saw it being compared to an Intel Arc Pro B60 or B70 (probably somewhere between the 2), but much like the Intel Battlemage cards, it’s no slouch either - I am actually quite happy with it. It is a Radeon RX6800XT with double the VRAM (or a Radeon Pro W6800 with no physical output) meant as cloud gaming GPUs, and certain higher-end Azure vDesktop instances use the V620 as their GPU to boost video playback. I like the idea of having an AI accelerator on an eGPU dock that I can toggle off remotely to save on power and noise. The fact that I got 32GB of GDDR6 VRAM (360 USD acepted offer+20 for the fan/shroud + S&H) for less than the price of 32GB of DDR5 SODIMM (419+S&H) and got a large bunch of RDNA2 compute shaders tossed in for free is...quite amusing to me. Why yes, I did have to spend 150 more on that dock, but it can be reused with another card.

What about power efficiency? Well, that will require me to compare the amount of power used versus the observed speedup in the AI compute tasks. The problem is that I don't really have an easy way to pull a total power consumed on a GPU based on a specific workload, whether it's iGPU or discrete GPU off a dock. I can look at amdgpu_top and guess from its socket power pull statistics, fudge a static wattage number (even though compute shader usage differs throughout the run)...then extrapolate it to the measured run time for a simple and naive power usage figure...

POWER/EFFICIENCY (BEST GUESSES,TAKE IT WITH FLAKES OF SEL DE GUERANDE )

All figures are given as multiples over the ones obtained over the 780M -

Wattage, V620 ROCm versus 780M VulkanSpeedup, V620 ROCm versus 780M VulkanWattage V620 Vulkan versus 780M VulkanSpeedup, V620m versus 780M VulkanEffficiency, 780M Vulkan versus V620 ROCmEffficiency, 780M Vulkan versus V620 Vulkan
Gemma-4-E2B-it-GGUF
3.469387755​
3.086206897​
3​
2.701886792​
1.28406111​
0.972067039​
Gemma-4-E4B-it-GGUF
3.469387755​
3.483028721​
3.265306122​
3.237864078​
1.071505064​
0.937490438​
Gemma-4-12B-it-GGUF
3.4​
4.103861518​
3.1​
3.966537967​
0.857170668​
0.755386113​
Gemma-4-12B-it-MTP-GGUF
3.4​
3.735632184​
3.2​
3.344768439​
1.016512821​
0.856615385​
Ministral-3-3B-Instruct-2512-GGUF
4.166666667​
3.537414966​
4.375​
3.391304348​
1.228632479​
1.236778846​
Nemotron-3-Nano-30B-A3B-GGUF
3.645833333​
3.820895522​
3.958333333​
3.67816092​
0.991210938​
1.035970052​
Qwen3.6-27B-MTP-GGUF
4.897959184​
4.21112023​
5​
3.854460094​
1.270725099​
1.187332521​
Qwen3.6-35B-A3B-GGUF-Q4_K_M
4.583333333​
4.236509759​
4.583333333​
3.385321101​
1.353884372​
1.081865402​
Qwen3.6-35B-A3B-MTP-GGUF
3.8​
3.642172524​
3.32​
3.081081081​
1.233333333​
0.91154386​
Qwen3-Coder-Next-REAM-i1-GGUF-Q3_K_M
3.06122449​
3.374649205​
3.06122449​
2.738140417​
1.117993975​
0.907123764​
gpt-oss-20b-mxfp4-GGUF
3.673469388​
4.234113712​
4.387755102​
3.95625​
0.928523068​
1.036286553​
Wattage, V620 ROCm versus 780M ROCmSpeedup, V620 ROCm versus 780M ROCmWattage, V620 Vulkan versus 780M ROCmSpeedup, V620 Vulkan versus 780M ROCmEffficiency, 780M ROCm versus V620 ROCmEffficiency, 780M ROCm versus V620 Vulkan
Gemma-4-E2B-it-GGUF
3.4​
2.981132075​
2.94​
3.405172414​
1.140506329​
0.863392405​
Gemma-4-E4B-it-GGUF
3.469387755​
3.54368932​
3.265306122​
3.812010444​
0.979032709​
0.856583729​
Gemma-4-12B-it-GGUF
3.4​
4.319176319​
3.1​
4.468708389​
0.787187128​
0.693712753​
Gemma-4-12B-it-MTP-GGUF
3.4​
4.805145798​
3.2​
5.366666667​
0.707574784​
0.596273292​
Ministral-3-3B-Instruct-2512-GGUF
3.921568627​
3.753623188​
4.117647059​
3.915343915​
1.044742221​
1.051669316​
Nemotron-3-Nano-30B-A3B-GGUF
3.5​
4.431034483​
3.8​
4.602985075​
0.789883268​
0.825551232​
Qwen3.6-27B-MTP-GGUF
4.8​
5.246948357​
4.9​
5.73245794​
0.914817466​
0.854781675​
Qwen3.6-35B-A3B-GGUF-Q4_K_M
4.4​
3.041284404​
4.4​
3.805970149​
1.446757164​
1.156078431​
Qwen3.6-35B-A3B-MTP-GGUF
3.8​
3.093366093​
3.32​
3.656694743​
1.228435266​
0.907923749​
Qwen3-Coder-Next-REAM-i1-GGUF-Q3_K_M
3​
2.948766603​
3​
3.634237605​
1.017374517​
0.825482625​
gpt-oss-20b-mxfp4-GGUF
3.6​
4.115625​
4.3​
4.404682274​
1.143229167​
1.024344715​

(Honestly, I didn't expect the numbers to change too much)

TESTING METHODOLOGY
Well, it's based on timing 5 runs of the tests above while keeping an eye on the GPU power figure on amdgpu_top. However, since different parts of the GPU (shader/assembler/runlist controller/backend interface) is used/dismissed during the process the compute figure can only be a rough guess over the span of the elapsed time. In general the power used (in watts) is multiplied by the elapsed time (in seconds), then divided by 3600 to get the approximate energy (in watt-hours) consumed. The energy consumed by a given backend of a GPU can then be compared as a ratio.


How do you read this?
The V620 consumes between 175 to 330W during the run, compared to the almost constant 47-54 W of the 780M (the V620 takes up 3.5 to 5x the power usage of the 780M, averaging about 4.2x), and the speedup is usually around 2-4.5x (averaging about 3.3x)...so we can derive the relative efficiency, and for anything over 1, it indicates that the 780M used up less power versus the V620, and if it's below 1, the V620 used less power versus the 780M. The numbers were actually closer than I would expect, but with the pattern suggesting that ROCm on the V620 being almost always less efficient than Vulkan on the 780M.

So what am I using it for? Well, mostly to mess around with local LLMs and to justify the purchase of this piece of hardware after the machine it was supposed to replace...failed to die yet again. It’s not like I plan to train a new frontier model with it.
 
Last edited:
  • Like
Reactions: marcoi

marcoi

Well-Known Member
Apr 6, 2013
1,724
418
83
Gotha Florida
@WANg i like it a lot. even the lego planes lol.

im kind of glad i didnt end up selling the n5pro before the end of PCs came about.
It running like a champ.
I did move the ubuntu VM off the n5pro to my Xen stack so i can bump the memory of the VM up and also give the iGPU 32GB of the 96gb ram on the n5pro.

  • U26 VM running hermes with three gateways.
  • One for local terminal, two setup with telegram bots with roles for an assistant and for development.
  • Right now running i am running the following llm setup
  • b70 complied llama.cpp with intel oneapi sync and Qwen3.6-35B-A3B-Q4_K_M.gguf
  • igpu running llama.cpp download vulkin and gpt-oss-20b-MXFP4.gguf
  • Lemonaid server runing flm npu with embed-gemma-300m and gemma4-it-eb4
Anyways i like to tinker with this stuff so im constantly trying to optimize.
I been toying with idea of take an old amd 5950 with 128GB ram and putting my 5090 and b70 into it and running models off that system. but then the power kind of kills it for me. its probably 1200 watt system vs the n5pro with b70 running like 380w.
 

fasting

New Member
Jan 24, 2017
6
4
3
39
seems like a used AMD Radeon Pro V620 32 gb can be had for 400-500 range if it fits your budget/components. I was considering getting one to play with but my current setup seems to be dialed in enough where im happy enough with it.
Thanks for the tip. Unfortunately the European second-hand market is not that great but I will keep an eye on it. Still just messing around so no hurry. Hopefully a good sale will pop up.
 

Greg_E

Active Member
Oct 10, 2024
564
177
43
I'll ask here since this is kind of a generic AI hardware thread:

I have 3 HP DL360p with 20 cores of Xeon v2 (I forget the model number), and 128GB DDR3ecc each. They are mostly wasted because of the lack of UEFI, they can't run some of the OS that I want to run on them, but pretty sure I can still get openSUSE running. Toying with building a slow LocalAI cluster. I do have a couple of old Quadro M2000 cards, not sure they will be worth keeping, also have some old Quadro K1200 cards. On to the questions:

Best OS? OpenSUSE Tumbleweed, LEAP, or LEAP Micro?

Is there a single slot video card that would be worth adding to these to give a little more performance, also hopefully pretty cheap? I have 1 3.0x16 slot and one 3.0x8 slot available in each host, the x8 is half height. [edit] looks like older GPU with Vulcan might be worth looking into [/edit]

Or too old, don't bother?

These sit here off/idle, so not looking to buy a bunch of new stuff, new stuff would go to Harvester HCI if I can find anything.
 
Last edited:

marcoi

Well-Known Member
Apr 6, 2013
1,724
418
83
Gotha Florida
I'll ask here since this is kind of a generic AI hardware thread:

I have 3 HP DL360p with 20 cores of Xeon v2 (I forget the model number), and 128GB DDR3ecc each. They are mostly wasted because of the lack of UEFI, they can't run some of the OS that I want to run on them, but pretty sure I can still get openSUSE running. Toying with building a slow LocalAI cluster. I do have a couple of old Quadro M2000 cards, not sure they will be worth keeping, also have some old Quadro K1200 cards. On to the questions:

Best OS? OpenSUSE Tumbleweed, LEAP, or LEAP Micro?

Is there a single slot video card that would be worth adding to these to give a little more performance, also hopefully pretty cheap? I have 1 3.0x16 slot and one 3.0x8 slot available in each host, the x8 is half height.

Or too old, don't bother?

These sit here off/idle, so not looking to buy a bunch of new stuff, new stuff would go to Harvester HCI if I can find anything.
if you have time to play with these servers, then tinker with them.
As for AI the vid cards wont be much help. you might get away with a super tiny llm.
which may be okay if you just want to play with learning software like llama.cpp etc.
If you can get a modern card with 12gb ram, the pci x16 slot should work for the card but with limited bandwidth. So loading llm model will take longer for example, but once loaded into vram it shouldnt matter much about the pci speed. Just be careful if you get a card that requires resizable bar support like intels cards. I doubt your old servers have that feature.
As for OS, have you tried installing something like proxmox to run other OS that need UEFI via VMS?
Other thing to consider with these old servers is noise and power usage.